How AI Classifiers Work - A Plain-Language Guide to How AI Classification Works
What an AI Classifier Actually Does
An AI classifier is a machine learning model that takes an input, such as a text message, an image, or a row of transaction data, and assigns it to one or more predefined categories. The model doesn't reason through a problem the way a human does. It detects patterns in the input and maps those patterns to the category that fits best.
A spam filter is the classic example. The model reads an incoming email and decides: spam or not spam. A fraud detection system looks at a card transaction and flags it as suspicious or legitimate. Both are classifiers doing the same fundamental job, just on different data.
What Are Classification Algorithms in AI
Classification algorithms are the mathematical procedures that teach a model to sort inputs into categories by learning from labeled examples. The most common families include logistic regression, decision trees, support vector machines, and neural networks. Each one draws a different kind of boundary between categories in the data.
Neural network-based classifiers dominate most text and image tasks today because they handle unstructured data well. Simpler algorithms like logistic regression still appear in production systems where explainability and speed matter more than raw accuracy. The right algorithm depends on the data type, the number of categories, and how much labeled training data is available.
Supervised Learning - the Standard Approach
Most classifiers are trained using supervised learning. You supply the model with thousands of examples, each one already labeled with the correct category, and it adjusts its internal parameters until it can reproduce those labels reliably. Most supervised text classifiers require at least a few hundred labeled examples per class to perform well, and complex real-world tasks often need far more.
Zero-shot and few-shot classifiers, typically built on large language models, can work with far fewer labeled examples by drawing on pre-trained knowledge. That flexibility comes with a trade-off: they are slower and more expensive to run at scale than a dedicated lightweight classifier.
How Classifiers Work in AI
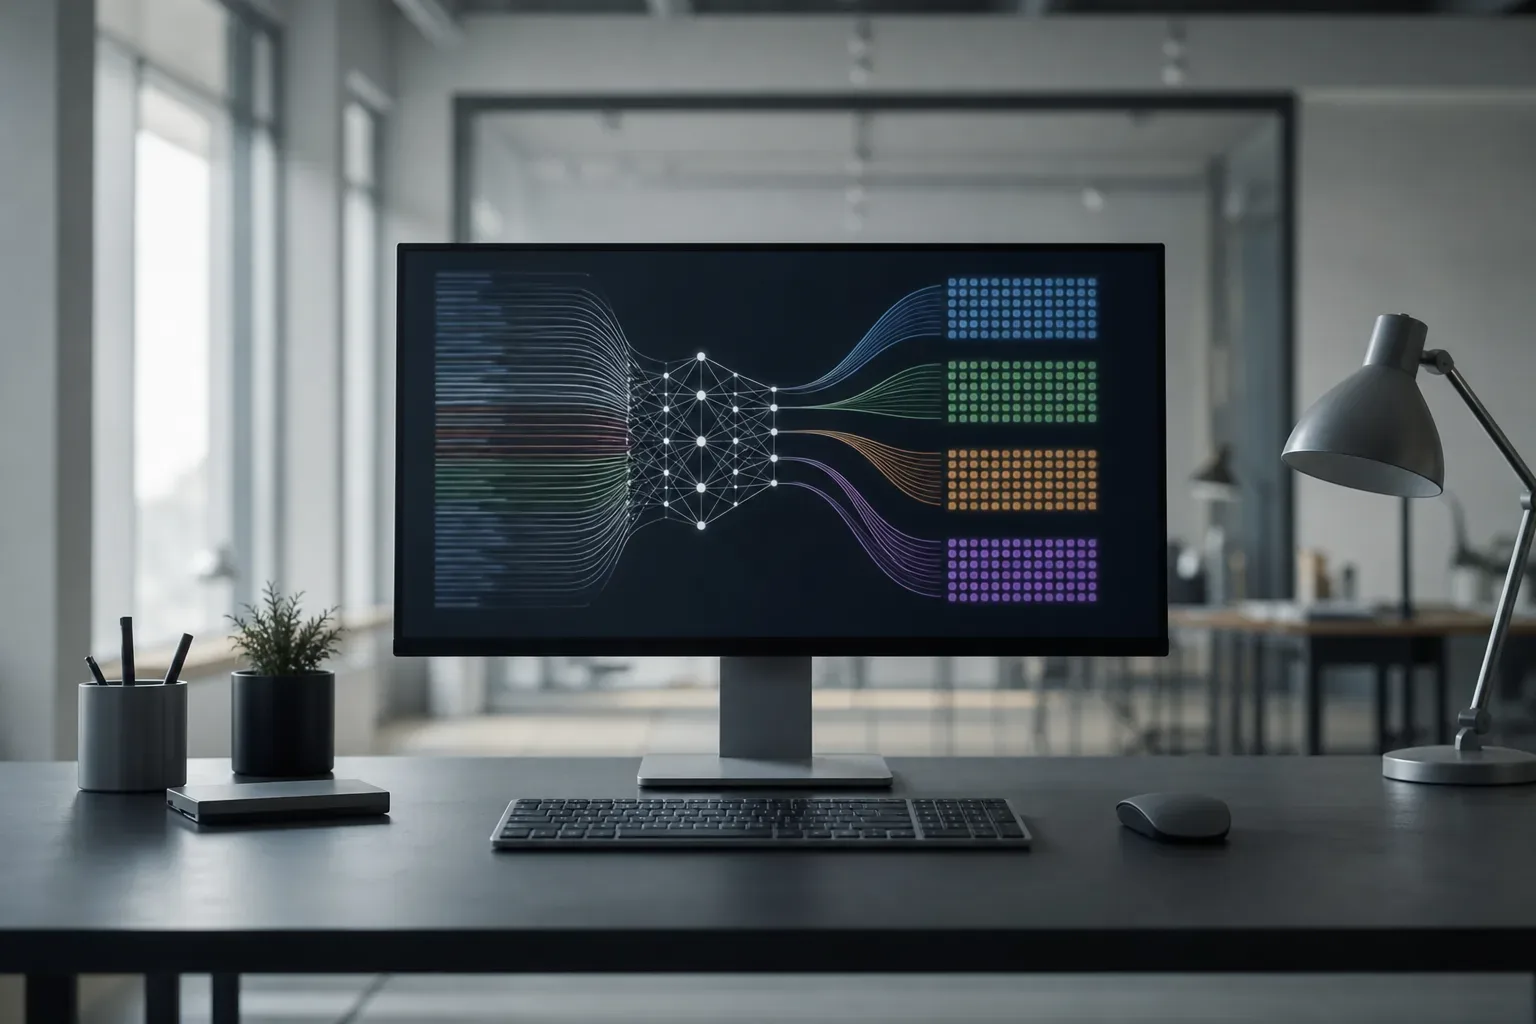
A classifier processes input by converting it into a numerical representation, running that representation through its learned parameters, and outputting a confidence score for each possible category. A confidence score is a probability value between 0 and 1, where a value close to 1 means the model is highly certain the input belongs to that class, and a value close to 0 means it almost certainly doesn't.
The model then applies a threshold to decide which label to commit to. The default threshold is 0.5: any class scoring above that value gets the positive prediction. Developers frequently adjust this cutoff depending on the stakes involved. A fraud detection system might lower the threshold to catch more suspicious transactions, even if that means flagging a few legitimate ones.
Multi-Class vs. Multi-Label Classification
Multi-class classification assigns exactly one label to each input from three or more possible classes. A news article classifier that picks one topic, such as politics, sports, or technology, from a fixed list is multi-class.
Multi-label classification allows a single input to receive two or more labels at the same time. A product description might be tagged as both "electronics" and "gift idea" simultaneously. These two setups look similar from the outside but require different training strategies and evaluation methods.
What Happens Inside the Model During Training
During training, the model makes predictions on its labeled examples and compares them to the correct answers. A loss function measures how wrong the predictions are. The model updates its internal weights to reduce that loss, repeating the process across many batches of data.
This cycle continues until performance on a held-out validation set stops improving. At that point, the model has learned to generalize: it can categorize new inputs it has never seen before, not just the ones it trained on. How well it generalizes depends on the quality and diversity of the training data, not just the volume.
Feature Extraction and Embeddings
Raw text can't go directly into a mathematical model. The classifier first converts words or sentences into dense numerical vectors called embeddings. These vectors capture semantic meaning: words with similar meanings sit close together in the vector space.
Image classifiers do something analogous. Convolutional layers extract edges, textures, and shapes at increasing levels of abstraction before the final classification layer makes its decision. This feature extraction step is often where the most training effort and compute cost are spent.
How Accuracy and Errors Are Measured
Accuracy alone rarely tells the full story. A classifier that correctly labels 99% of emails as not-spam looks great on paper, but if spam makes up only 1% of the inbox, the model could achieve that score by predicting "not spam" every single time. Practitioners use precision, recall, and F1 scores to get a clearer picture.
Modern AI spam classifiers commonly report 95–99% accuracy on benchmark datasets, though real-world performance depends heavily on data freshness and domain specifics. False positives and false negatives carry different costs. Production fraud classifiers typically target a false positive rate below 1–5%, because incorrectly blocking a legitimate transaction damages customer trust.
Why Classifiers Are Often Preferred Over Large Language Models
Dedicated classifiers are generally faster and cheaper to run at scale than prompting a large language model for the same binary or multi-class decision. Most cloud-hosted text classifiers respond in under 100 milliseconds at standard input lengths. An LLM-based approach might take several seconds and cost an order of magnitude more per call.
Indicative API pricing for managed classifier services runs from $0.50 to $5.00 per 1,000 calls depending on model size and input length. That makes classifiers the practical default for high-volume tasks like content moderation, where large platforms process hundreds of millions of items per day before any human review gets involved. LLMs earn their keep when flexibility and nuanced reasoning matter more than throughput.
Classifiers as Safety Layers
Many AI systems now embed classifiers as guardrails: safety layers that inspect inputs or outputs to block harmful, off-topic, or non-compliant content before it reaches end users. A customer service chatbot might use a classifier to detect if an incoming message is abusive, routing it away from the main model entirely.
This architectural pattern keeps the core system clean without slowing it down significantly. The guardrail classifier runs in parallel or just ahead of the main pipeline, adding a modest latency cost for a meaningful reduction in risk. The EU AI Act, in force from 2024 with phased obligations running through 2027, designates certain AI classification systems as high-risk, requiring conformity assessments and documented human oversight for those specific use cases.
Frequently Asked Questions
What Are Classification Algorithms in AI?
Classification algorithms are the mathematical procedures that train a model to sort inputs into categories by learning from labeled examples. Common families include logistic regression, decision trees, support vector machines, and neural networks. Neural network-based classifiers dominate text and image tasks today, while simpler algorithms remain popular where speed or explainability is the priority.
How Do Classifiers Work in AI?
A classifier converts its input into a numerical representation, passes that through its trained parameters, and outputs a confidence score between 0 and 1 for each possible category. A score close to 1 means high certainty the input belongs to that class. The model then applies a threshold, typically 0.5 by default, to decide which label to assign, though developers often tune this cutoff to suit the specific cost of errors in their application.
How Much Training Data Does an AI Classifier Need?
Most supervised text classifiers need at least a few hundred labeled examples per class to achieve reliable performance. Complex real-world tasks with many categories or noisy data typically require thousands of examples. Zero-shot and few-shot classifiers built on large language models can operate with far fewer examples, but they are slower and more expensive to run at scale.
What Is the Difference Between Multi-class and Multi-label Classification?
Multi-class classification assigns exactly one label to each input from three or more possible categories, for example deciding whether a news article covers politics, sports, or technology. Multi-label classification allows a single input to receive two or more labels at once, such as tagging a product as both 'electronics' and 'gift idea'. The two setups require different training strategies and evaluation methods even though they look similar from the outside.
Are AI Classifiers Accurate Enough for Real-world Use?
Modern AI spam classifiers commonly report 95–99% accuracy on benchmark datasets, though real-world performance depends on data freshness and how closely the deployment domain matches the training data. Accuracy is rarely the only metric that matters: precision, recall, and false positive rate are equally important. Production fraud classifiers, for instance, typically target a false positive rate below 1–5% to avoid blocking legitimate customer transactions.