Binary Classification - Yes/No Decisions with AI
What Binary Text Classification Actually Does
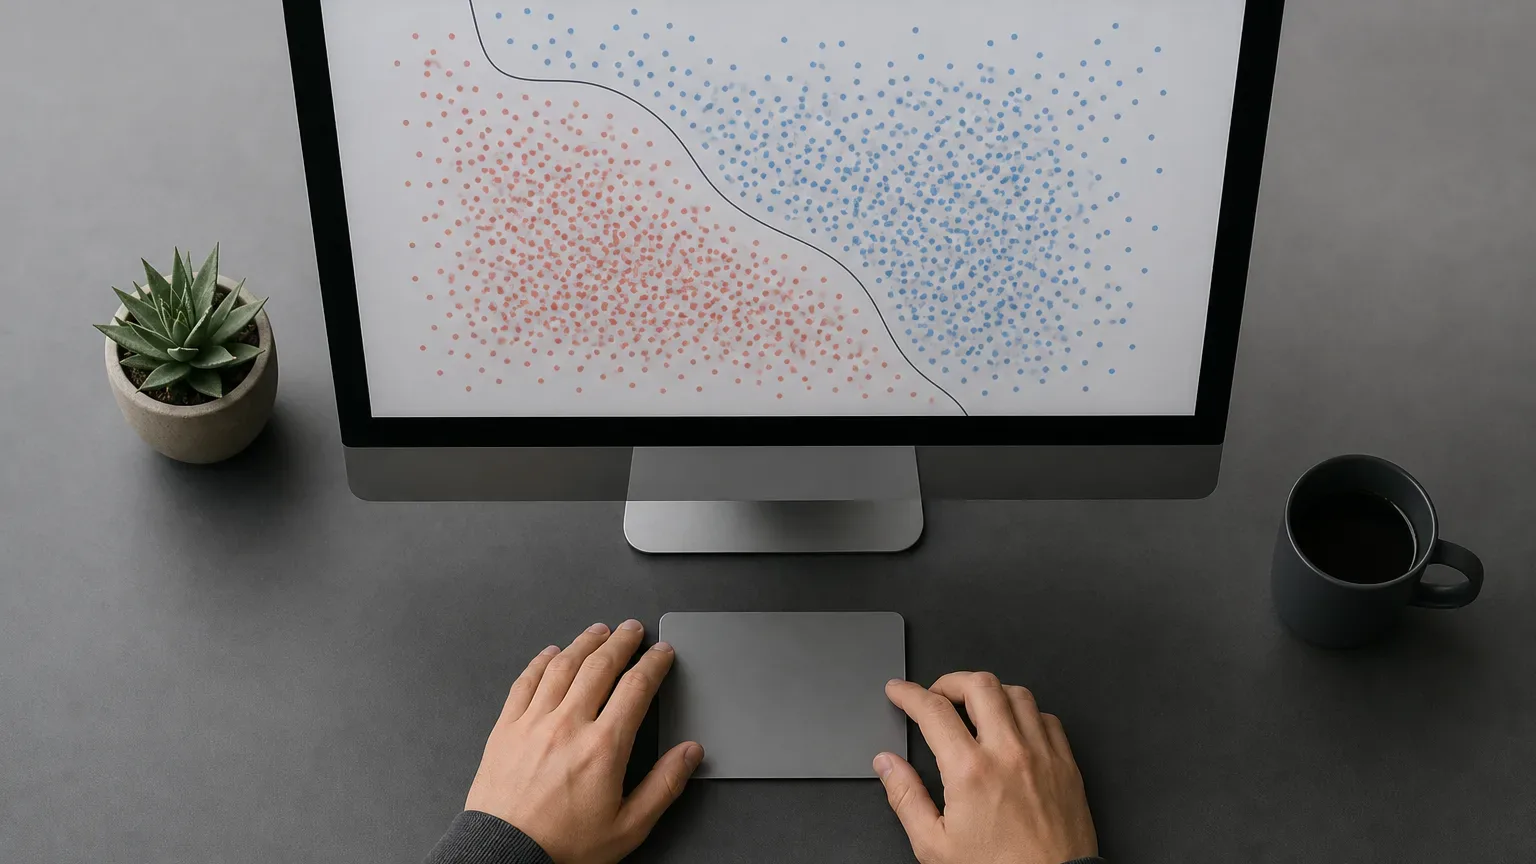
Binary text classification is a machine learning approach that reads a piece of text and assigns it to exactly one of two categories, most commonly represented as yes/no, positive/negative, or spam/not spam. Every email inbox that filters junk mail, every review platform that flags offensive comments, and every customer service tool that detects angry messages relies on this same basic mechanism. The model draws a decision boundary, a mathematical line that divides the feature space into two regions. Text that falls on one side gets one label; text on the other side gets the other.
That boundary is not drawn arbitrarily. During training, the model processes hundreds or thousands of labeled examples and adjusts its internal parameters until the boundary reliably separates the two classes. A well-trained boundary produces few errors. A poorly trained one bleeds examples from one class into the other.
The Decision Boundary Explained
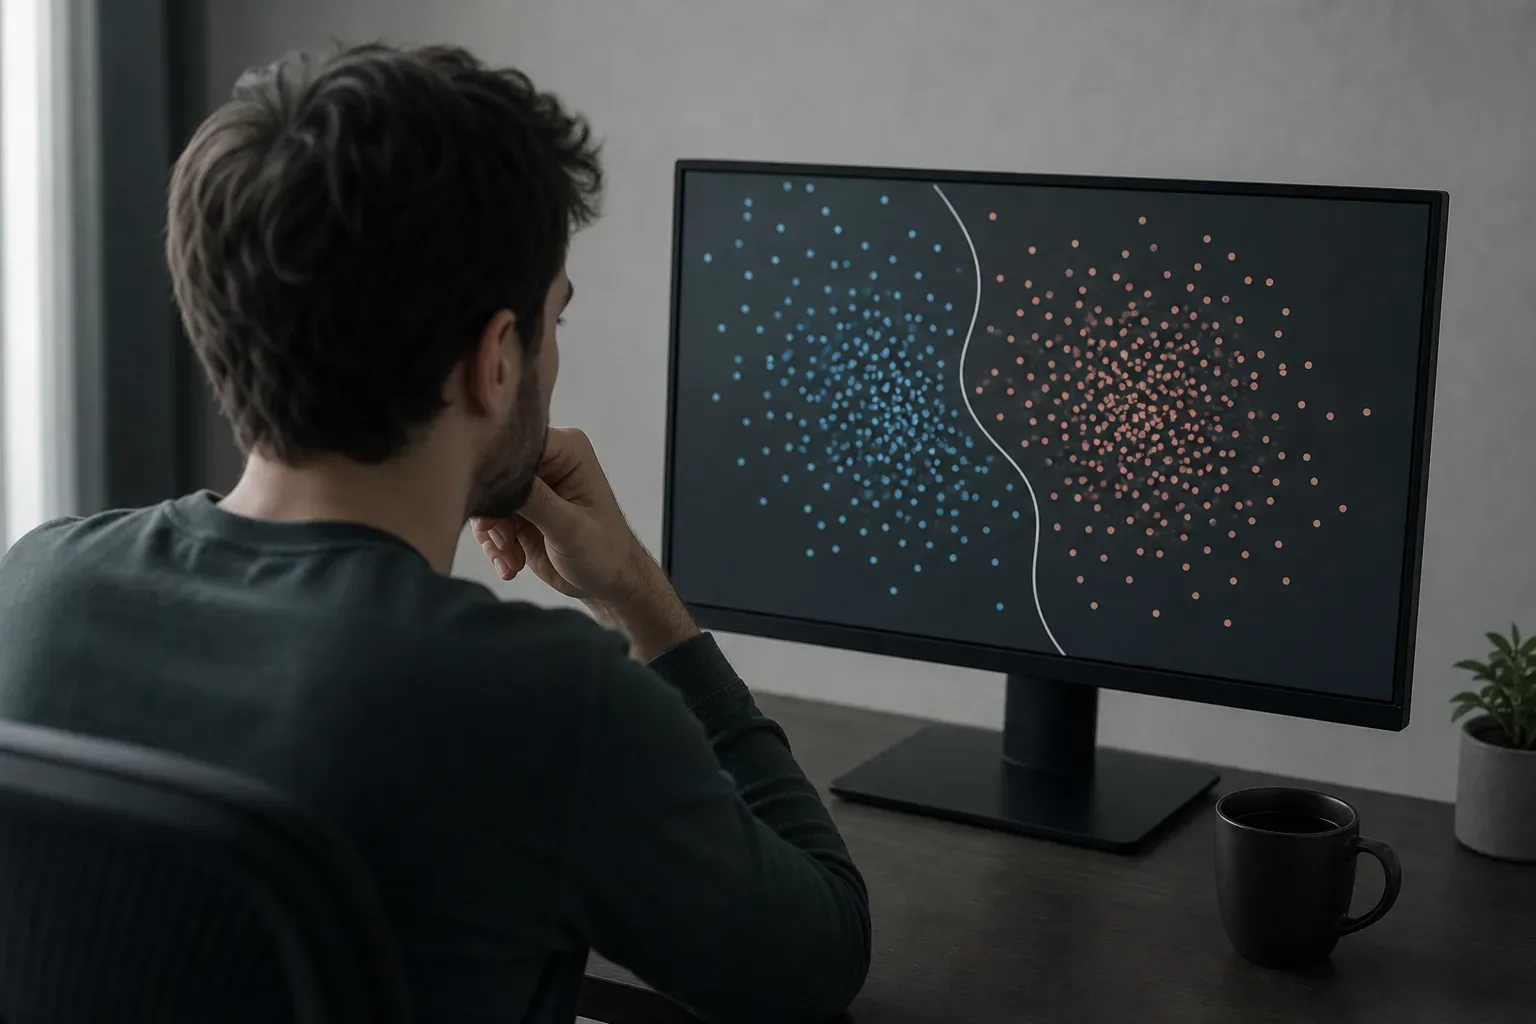
Picture a scatter plot where every dot represents a piece of text. The model converts each text into a set of numbers based on word patterns, tone, and structure, then positions it on that plot. The decision boundary is the line (or curve, in more complex models) that separates the two clusters.
Texts far from the boundary are classified with high certainty. Texts sitting close to it could plausibly belong to either class, so the model expresses less certainty. This is where the confidence score becomes useful. Each prediction comes with a confidence score, a probability value between 0 and 1 indicating how likely the input belongs to a given class.
A score close to 1 means the model is highly confident; a score close to 0 means the opposite.
Why the Threshold Matters
The threshold is a confidence score cutoff, commonly 0.5 by default, above which a classifier commits to a positive prediction. Setting it at 0.5 means any text with a confidence score above that value gets labeled positive. That default is not always the right choice.
A fraud detection system might lower its threshold to catch more suspicious transactions, accepting some false positives to reduce missed fraud. A content recommendation system might raise its threshold to avoid incorrectly flagging legitimate posts. Threshold tuning is one of the most practical levers engineers use to balance precision and recall after a model is already trained.
How the Model Learns the Boundary
Supervised binary classifiers learn from labeled data. Someone, usually a human annotator, reads each training example and marks it as belonging to class A or class B. Modern supervised text classifiers require at least a few hundred labeled examples per class to achieve reliable performance, though more data almost always improves results.
Once trained, the model encodes patterns it found in those examples: specific words, phrases, sentence lengths, punctuation patterns, or sentiment cues that reliably predict one class over the other. A spam classifier might learn that messages containing certain phrases alongside urgent language almost always belong to the spam class. The boundary shifts to reflect that pattern.
Zero-Shot and Few-Shot Alternatives
Not every project starts with hundreds of labeled examples. Large language model-based approaches can perform binary classification with few or no labeled training examples, using the model's pre-trained language understanding to make predictions from instructions alone. This flexibility comes with a trade-off: dedicated classifiers are generally faster and cheaper to run at scale than prompting a large language model for the same binary decision, often by an order of magnitude per inference. For high-volume pipelines processing millions of texts daily, that cost difference becomes significant quickly.
Real-World Performance Benchmarks
For well-studied binary classification problems like spam detection, modern AI classifiers commonly report 95–99% accuracy on benchmark datasets. Real-world accuracy depends on domain freshness, data quality, and how the threshold is set. A classifier trained on last year's phishing emails may underperform on this year's tactics.
Cloud-hosted text classifiers typically respond in under 100 milliseconds at standard input lengths, making them practical for real-time applications. Pricing for managed classifier APIs typically runs $0.50–$5.00 per 1,000 API calls depending on model size, provider, and input length. Building a custom supervised classifier from scratch, including data labeling, training, evaluation, and deployment, typically costs $5,000–$50,000 or more depending on complexity and team location.
Where Binary Text Classification Gets Used
The same underlying mechanism appears across industries, just with different labels on each side of the boundary.
Customer support triage classifies incoming messages as urgent or non-urgent, routing the urgent ones to live agents immediately. Sentiment analysis reads product reviews and outputs positive or negative, giving brands a fast signal at scale. Compliance screening reads financial communications and flags those that may contain insider information. Medical intake tools classify patient-submitted notes as requiring immediate follow-up or routine scheduling.
In each case, the binary output feeds into a larger workflow. The classifier does not make the final decision; it filters and routes so that humans or downstream systems work on the right subset of inputs.
Guardrails and Safety Layers
A guardrail is an AI safety layer, implemented as a classifier or rules engine, that inspects inputs or outputs to block harmful, non-compliant, or off-topic content before it reaches end users. Most guardrails in production LLM applications are binary classifiers running in the background: is this input a prompt injection attempt, yes or no? Is this output sexually explicit, yes or no?
Because binary classifiers run fast and cheaply, they suit this role well. A guardrail that added 500 milliseconds to every response would be unusable; one that adds under 100 milliseconds typically is not noticed. Stacking multiple binary classifiers in sequence lets a product screen for several harm categories without a significant latency penalty.
Regulatory Considerations
The EU AI Act, in force from 2024 with phased obligations running through 2027, designates certain AI classification systems as high-risk, requiring conformity assessments and human oversight. Binary classifiers used in hiring, credit scoring, or law enforcement decisions fall into this category. Compliance deadlines continue to shift, so verifying current requirements before deploying any high-stakes classifier is essential.
Even outside regulated industries, documenting how a decision boundary was constructed and what training data was used builds a practical audit trail. When a classifier makes an error on a consequential decision, that documentation shortens the investigation considerably.
Frequently Asked Questions
What Are Some Binary Text Classification Examples?
Common examples include spam vs. not spam in email filtering, positive vs. negative in product review sentiment analysis, urgent vs. non-urgent in customer support triage, and safe vs. harmful in content moderation. Each uses the same mechanism: a model draws a decision boundary and assigns every input to one of two classes.
What Is a Decision Boundary in Binary Classification?
A decision boundary is a mathematical line or curve that divides the model's feature space into two regions. Text that falls on one side receives one label; text on the other side receives the other. The model learns where to place that boundary by training on labeled examples.
What Does a Confidence Score Mean in Binary Classification?
A confidence score is a probability value between 0 and 1 indicating how likely the input belongs to a given class. A value close to 1 means the model is highly confident in its prediction; a value close to 0 means the opposite. Texts near the decision boundary typically produce scores close to 0.5, reflecting genuine uncertainty.
How Much Training Data Does a Binary Classifier Need?
Most supervised binary text classifiers require at least a few hundred labeled examples per class to achieve reliable performance. Zero-shot and few-shot approaches built on large language models can work with fewer examples, but dedicated classifiers trained on sufficient data generally outperform them on speed and cost at scale.
How Do You Choose the Right Classification Threshold?
The default threshold is 0.5, meaning any prediction with a confidence score above that value is classified as positive. You adjust it based on the cost of errors in your specific use case. Fraud detection often uses a lower threshold to catch more cases at the expense of more false positives; recommendation systems often use a higher one to avoid incorrectly flagging legitimate content.