AI Content Moderation Classifiers - How Platforms Filter Harmful Content
Every minute, millions of posts, images, and comments flood social platforms. No human team could review that volume in real time. AI content moderation classifiers sit between user submissions and public feeds, assigning each piece of content to categories like "safe," "hate speech," "spam," or "graphic violence" before most people ever see it.
What an AI Classifier Actually Does
An AI classifier is a machine learning model that assigns input data to one or more predefined categories. In content moderation, the input is a piece of text, an image, or a short video clip. The output is a label, paired with a confidence score: a probability value between 0 and 1 indicating how likely the content belongs to that category.
A score of 0.92 against a "harassment" class means the model is highly confident the content violates policy. A score of 0.48 sits below the typical default threshold of 0.5, so the classifier would pass that content through, possibly flagging it for secondary review rather than auto-removal. Platforms tune these thresholds carefully, because a lower threshold catches more violations but also generates more false positives.
How the Classification Pipeline Works
Content enters the pipeline the moment a user hits submit. The classifier processes it, usually returning a decision in under 100 milliseconds for standard text inputs on cloud-hosted systems. That speed matters enormously when a platform handles hundreds of millions of content items per day.
Ingestion and Preprocessing
Raw text gets cleaned first: encoding normalized, URLs extracted, and language detected. Images may be resized or converted to a standard format. This preprocessing step reduces noise that could distort the model's predictions.
Model Inference
The cleaned input passes through the trained classifier. Most modern systems use multi-label classification, meaning a single post can receive several labels at once. A comment might score high on both "spam" and "misinformation" simultaneously. Multi-label differs from multi-class classification, where each input receives exactly one label from a set of options.
Routing and Action
The confidence scores feed into a routing layer. High-confidence violations are auto-removed. Borderline cases route to a human review queue. Low-confidence passes go live but may receive lighter-touch monitoring, such as reduced algorithmic distribution.
Why Platforms Use Classifiers Rather Than Large Language Models
Dedicated classifiers are generally faster and cheaper to run at scale than prompting a large language model for the same binary or multi-class decision. A lightweight classification model typically costs an order of magnitude less per inference than an equivalent LLM API call. Across billions of daily decisions, that cost difference is decisive.
LLMs offer flexibility that classifiers lack. They can reason through ambiguous context and handle novel phrasing without retraining. Platforms often combine both: a fast classifier handles routine decisions at scale, and an LLM handles escalated edge cases where context is genuinely complex.
What Classifiers Are Trained to Detect
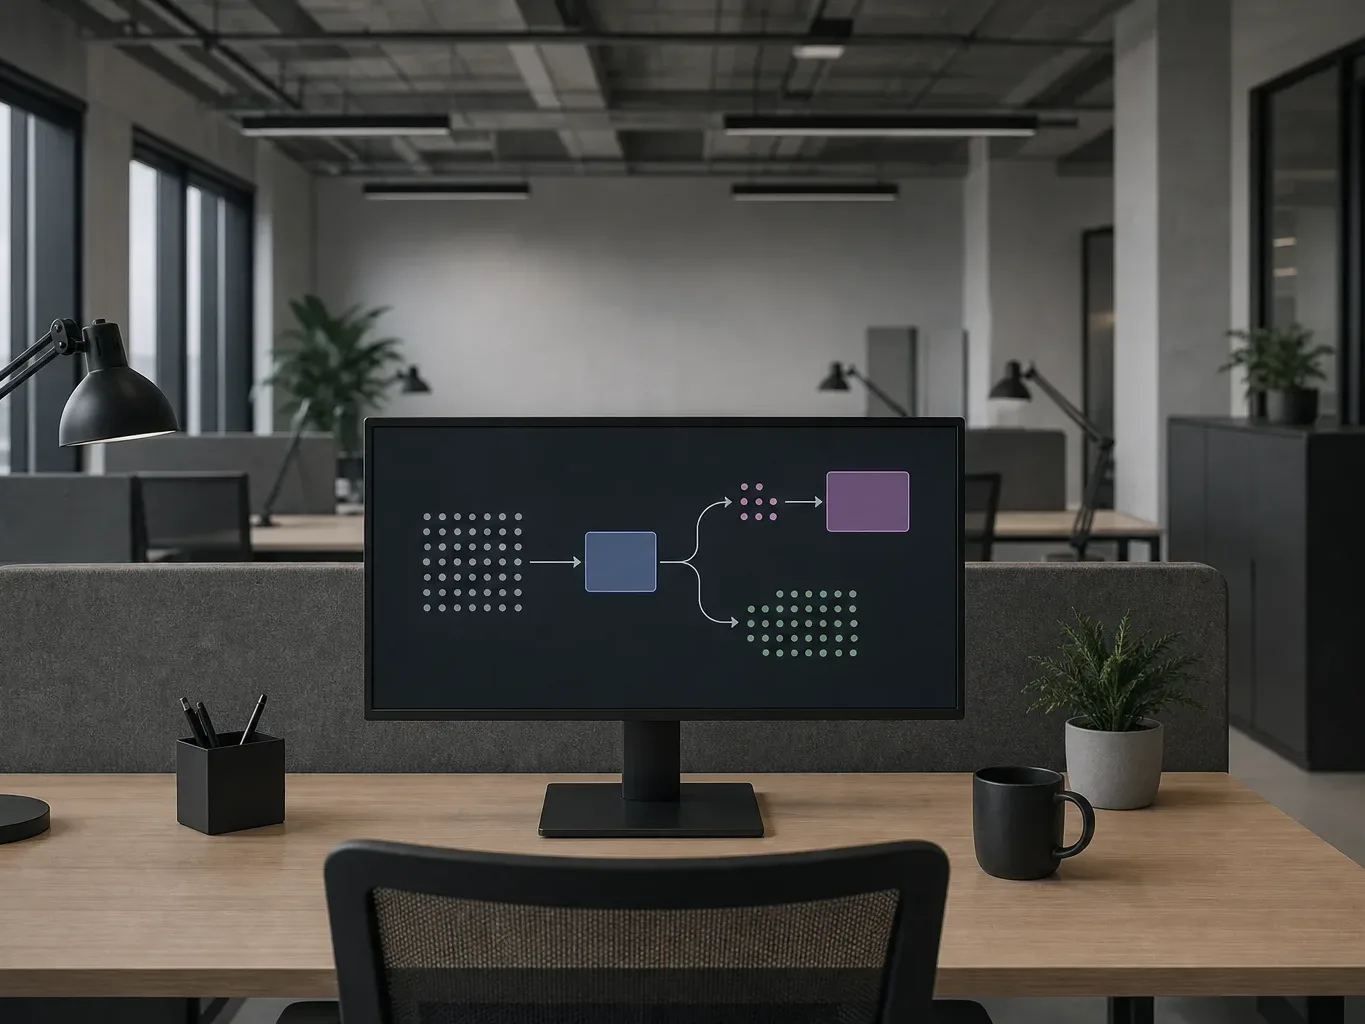
Modern AI content moderation classifiers cover a wide range of policy categories. Spam detection is the most mature use case. AI spam classifiers commonly report 95–99% accuracy on benchmark datasets, though real-world accuracy depends on how fresh the training data is and what threshold the platform sets.
Beyond spam, classifiers target hate speech, self-harm content, graphic violence, sexual content, and coordinated inauthentic behavior. Each category usually requires its own model or at minimum its own labeled training data. Most supervised text classifiers need at least a few hundred labeled examples per class to reach reliable performance, and production systems typically use thousands or tens of thousands.
Confidence Scores and Threshold Tuning
The default threshold of 0.5 is not always the right choice. A platform moderating content that affects children may drop the threshold to 0.3, accepting more false positives to ensure very little harmful content slips through. A platform focused on minimizing user friction might raise the threshold to 0.7, routing only high-confidence violations to removal.
Fraud and abuse classifiers face a different version of this problem. Production fraud classifiers typically target a false positive rate below 1–5%, because wrongly blocking a legitimate user has real business and reputational cost. Threshold decisions are policy decisions as much as technical ones.
Guardrails - the Safety Layer Around Classifiers
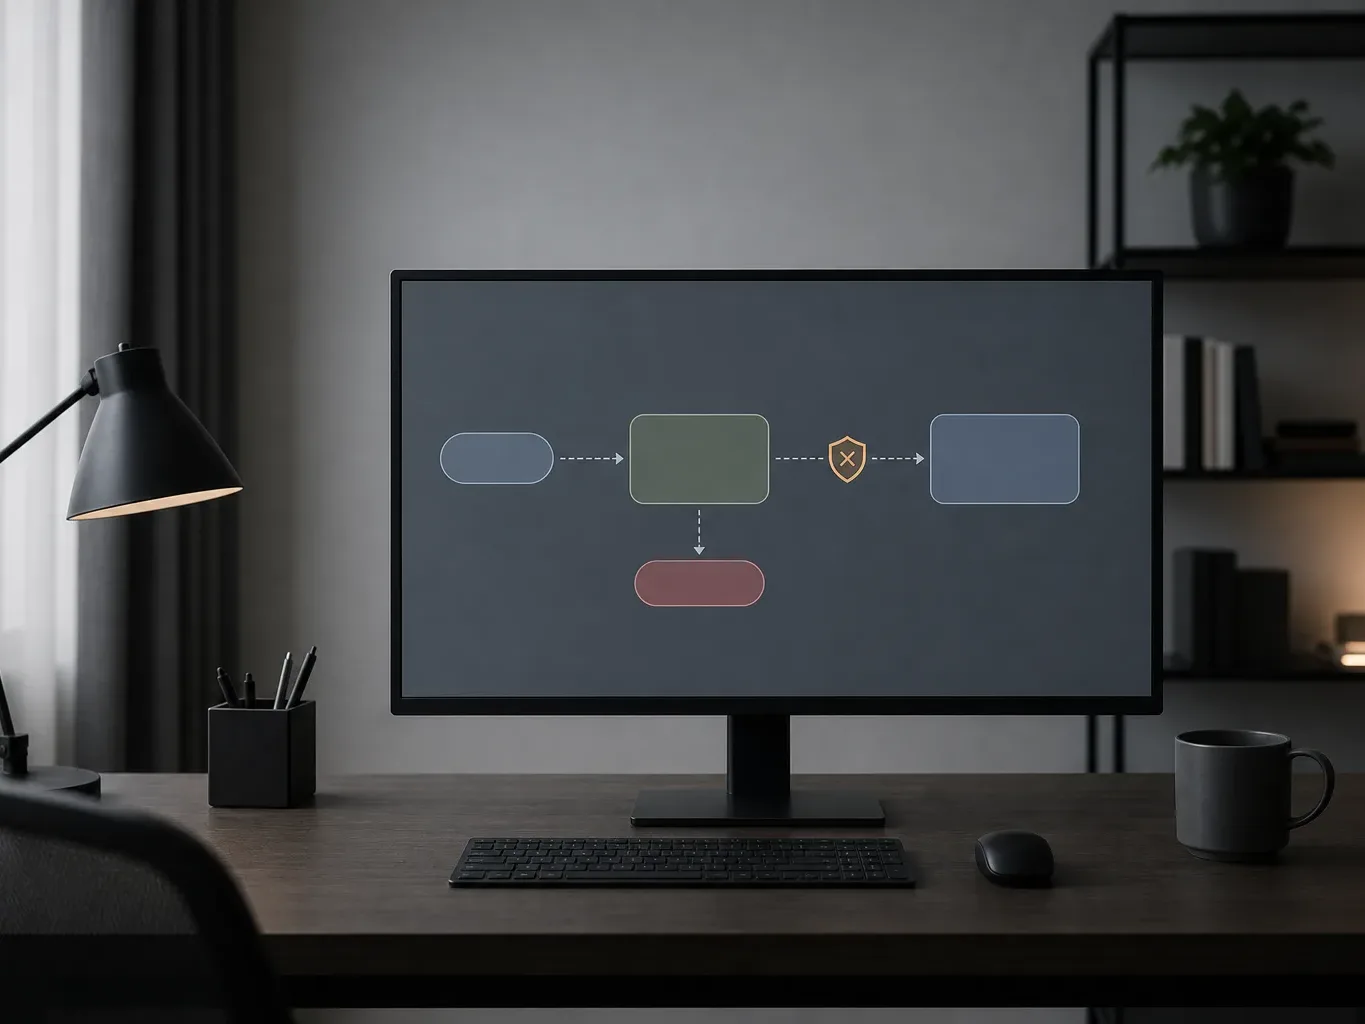
A guardrail is an AI safety layer, implemented as a classifier or rules engine, that inspects inputs or outputs to block harmful or off-topic content before it reaches users. On content platforms, guardrails often run in parallel with the main moderation classifier.
One common pattern is to run a fast rule-based guardrail first. If the content contains a known slur or a flagged URL, it is blocked immediately without consuming classifier resources. Content that passes the rule layer then moves to the classifier, which handles subtler violations. This two-stage approach keeps costs manageable without sacrificing coverage.
The Limits of Automated Classification
Accuracy figures from benchmark datasets rarely translate directly to production environments. Language evolves, bad actors adapt their phrasing, and cultural context shifts the meaning of the same words across communities. A classifier trained on data from one region may perform poorly on slang from another.
AI PII classifiers illustrate this gap clearly. They can identify common personal data types like names, emails, phone numbers, and national ID numbers, but should be combined with rule-based patterns for regulatory compliance. No classifier provides 100% coverage, and human audit remains essential for high-stakes decisions.
The EU AI Act, in force from 2024 with phased obligations running through 2027, designates certain AI classification systems as high-risk, requiring conformity assessments and human oversight. Platforms deploying classifiers in areas like employment content or credit-related decisions need to verify which obligations apply to their specific use case.
How Platforms Improve Classifiers Over Time
Models are not static. Platforms continuously collect new labeled examples from human reviewer decisions and feed them back into retraining cycles. When a new type of coordinated abuse campaign emerges, analysts label examples of it and queue a model update.
Active learning prioritizes the most uncertain examples for human labeling. Cases where the classifier scored close to 0.5, genuine toss-ups, are more informative for retraining than cases where the model was already confident. This approach stretches the labeling budget without sacrificing the quality of the updated model.
What This Means for Users
Content moderation classifiers operate invisibly for most users. A post that violates policy may simply not appear in feeds, or the poster may receive a notification citing the relevant community guideline. The classifier's confidence score and the platform's threshold setting determine which of those outcomes occurs.
Appeals processes exist precisely because classifiers make mistakes. When a user disputes a removal, a human reviewer examines the original content, the classifier's output, and the applicable policy. That human judgment can override the model, and the outcome often feeds back into future training data.
Frequently Asked Questions
Content Moderation Classifier - How It Works
A content moderation classifier is a machine learning model that takes a piece of text, image, or video as input and assigns it to one or more predefined policy categories, such as spam, hate speech, or graphic violence. Each prediction comes with a confidence score between 0 and 1. If the score exceeds the platform's threshold, typically set around 0.5 by default, the content is flagged for removal or human review. The whole process usually completes in under 100 milliseconds for standard text inputs on cloud-hosted systems.
How Accurate Are AI Content Moderation Classifiers at Detecting Harmful Content?
Modern AI spam classifiers commonly report 95–99% accuracy on benchmark datasets, but real-world accuracy is lower and depends on data freshness, the specific language and slang in use, and how the confidence threshold is set. Classifiers trained on one region's language patterns may perform less reliably on content from another community. Most platforms combine automated classifiers with human review queues for borderline cases to maintain acceptable accuracy in production.
What Is a Confidence Score in Content Moderation?
A confidence score is a probability value between 0 and 1 that the classifier outputs alongside each label, indicating how likely the content belongs to that category. A score of 0.92 against a 'harassment' class means the model is highly confident the content violates policy, while a score of 0.30 suggests low confidence. Platforms set a threshold, commonly 0.5 by default, above which the classifier commits to a positive prediction and triggers an action such as removal or routing to a human reviewer.
Why Do Platforms Use Classifiers Instead of Large Language Models for Moderation?
Dedicated classifiers are generally faster and cheaper to run at scale than prompting a large language model for the same binary or multi-class decision. A lightweight classification model typically costs an order of magnitude less per inference than an equivalent LLM API call, which matters enormously across billions of daily content decisions. LLMs offer more flexibility for ambiguous or novel cases, so many platforms use a hybrid approach: classifiers handle routine decisions at volume, and LLMs handle escalated edge cases where richer context is needed.
What Regulations Apply to AI Content Moderation Classifiers in Europe?
The EU AI Act, in force from 2024 with phased obligations running through 2027, designates certain AI classification systems as high-risk and requires conformity assessments along with mandatory human oversight. Whether a content moderation classifier falls into the high-risk category depends on the specific context in which it is deployed, such as employment-related content decisions or access to essential services. Platforms should verify current compliance deadlines with legal counsel, as the legislation's timelines and implementing rules continue to develop through the phased rollout period.