AI Guardrails and Safety Classifiers
Every time you type a message into an AI chatbot, a set of automated checks runs before the model ever responds. Those checks are AI guardrails: safety layers built from classifiers and rules engines that inspect what goes in, what comes out, and sometimes what actions an agent is about to take. Without them, AI products would be far easier to misuse, manipulate, or break in ways that harm real people.
What Are AI Guardrails
An AI guardrail is a safety layer, implemented as a classifier or rules engine, that inspects inputs or outputs to block harmful, non-compliant, or off-topic content before it reaches end users. The term covers a broad family of techniques, from simple keyword lists to sophisticated machine learning models that understand context and intent. A guardrail does not generate text or make decisions the way a large language model does. It assigns a category or a score and then acts on that result.
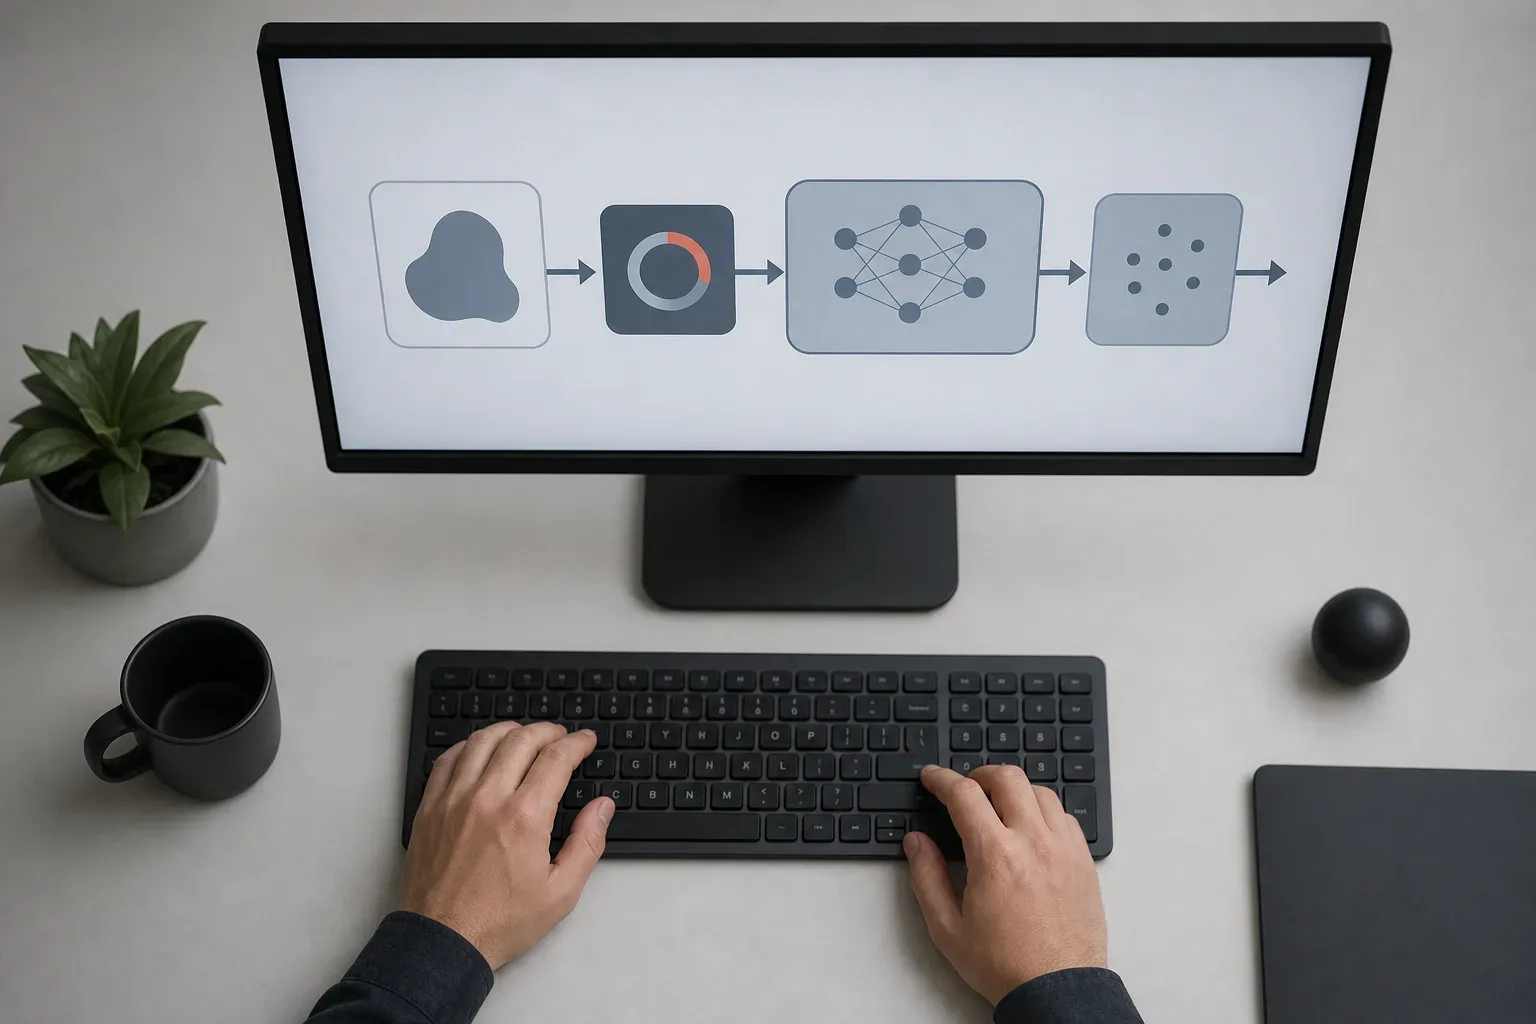
The underlying technology is an AI classifier: a machine learning model that assigns input data to one or more predefined categories. A guardrail classifier might categorize a user message as "safe," "harmful," or "ambiguous," then route each category to a different outcome. That outcome could be a normal response, a refusal, a human review queue, or a logged alert for later investigation.
AI Safety Guardrails Examples
Guardrails appear across almost every consumer-facing AI product today. A few concrete cases illustrate the range.
Content Moderation
Large platforms process hundreds of millions of content items per day using automated classifiers before any human review reaches those items. A content moderation guardrail checks user-generated posts, images, or comments for categories like hate speech, graphic violence, or self-harm. Confidence scores (probability values between 0 and 1) drive routing decisions: items scoring above a set threshold get held for review or removed automatically, while lower-scoring items pass through.
Spam and Fraud Detection
Email providers and payment processors run input-side guardrails that classify incoming data before any action is taken. Modern AI spam classifiers commonly report 95–99% accuracy on benchmark datasets, though real-world performance depends on how fresh the training data is and how the detection threshold is tuned. Fraud classifiers in financial services typically target a false positive rate below 1–5%, since flagging legitimate transactions costs customer trust and operational time.
Chatbot Topic Enforcement
A customer service bot for a retail brand should not start discussing competitor products, political topics, or medical advice. A guardrail classifier checks each user message against the bot's permitted topic scope and routes out-of-scope queries to a fallback response. This keeps the product focused and reduces legal and reputational risk for the operator.
PII Detection
AI PII classifiers can identify common personal data types, including names, emails, phone numbers, and national ID numbers. When a user accidentally pastes sensitive data into a chat interface, a guardrail can flag or redact it before the text reaches the model or gets stored in logs. Regulatory compliance still requires combining these classifiers with rule-based patterns and periodic human audits, since no classifier catches every case.
How Do AI Guardrails Work
Guardrails work by running a classifier against each piece of text (or other data) at a defined checkpoint in the AI pipeline, then taking a pre-configured action based on the result. Most production systems use at least two checkpoints: one on the input (what the user sends) and one on the output (what the model generates). Some agentic systems add a third checkpoint on the actions an AI agent is about to execute, such as making an API call or writing to a database.
At each checkpoint, the classifier outputs a confidence score for each category it monitors. A threshold, commonly 0.5 by default but usually tuned during deployment, determines whether the classifier commits to a positive prediction. Setting the threshold higher reduces false positives but lets more borderline harmful content through. Setting it lower catches more edge cases but increases the chance of blocking legitimate content.
Operators adjust this balance based on the specific risk profile of their product.
Input-Side vs. Output-Side Checks
Input-side guardrails focus on what users send. They defend against prompt injection, a recognized top security risk for LLM-powered applications according to the OWASP LLM Top 10, where an attacker embeds instructions designed to hijack the model's behavior. Catching these attempts before they reach the model is far more reliable than trying to fix a manipulated output afterward.
Output-side guardrails focus on what the model produces. Even a well-aligned model can occasionally generate text that is off-brand, factually wrong in a harmful way, or unexpectedly explicit. Running a second classifier over the response before it returns to the user provides a second line of defense without slowing down the experience noticeably. Most cloud-hosted text classifiers respond in under 100 milliseconds at standard input lengths, making this dual-layer approach practical at scale.
Why Dedicated Classifiers Rather Than Asking the Main Model
Dedicated classifiers are generally faster and cheaper to run at scale than prompting a large language model for the same binary or multi-class safety decision. Running a lightweight classification model typically costs an order of magnitude less per inference than an equivalent LLM API call. For a product handling millions of daily interactions, that cost difference is significant.
There is a real trade-off, though. LLMs offer flexibility that a fixed-category classifier cannot match, especially for novel attack patterns that fall outside the classifier's training distribution. Many production systems combine both: a fast classifier handles known categories at high volume, while a smaller LLM-based check handles ambiguous edge cases that the classifier flags for closer inspection.
Managed classifier APIs typically cost $0.50–$5.00 per 1,000 calls depending on model size, provider, and input length. Building a custom classifier from scratch runs $5,000–$50,000 or more for a full supervised project covering data labeling, training, evaluation, and deployment. The right choice depends on how specialized the risk categories are and how much data the operator can provide.
Regulatory Pressure and Human Oversight
The EU AI Act, in force since 2024 with phased obligations running through 2027, designates certain AI classification systems as high-risk. Those systems require conformity assessments and documented human oversight procedures. Guardrails help operators satisfy the oversight requirement, but they do not replace it. A logged, human-reviewable audit trail showing that the classifier flagged and acted on problematic content is part of what regulators expect to see.
Multi-label classification adds another layer of practical value here. A single message can simultaneously be flagged as off-topic and as a potential prompt injection attempt, since multi-label classification allows one input to receive two or more labels at the same time. Capturing that compound risk in a single pass is more efficient than running independent single-class checks in sequence.
Building responsible AI products means designing guardrails as a first-class architectural concern rather than an afterthought bolted on before launch.
Frequently Asked Questions
What Are AI Guardrails?
AI guardrails are safety layers, built from classifiers or rules engines, that inspect the inputs users send and the outputs an AI generates before either reaches its destination. They assign a category and a confidence score to each piece of content, then take a pre-configured action such as allowing, blocking, or flagging the content for human review.
AI Safety Guardrails Examples
Common examples include content moderation classifiers on social platforms that catch hate speech or graphic violence, spam and fraud detectors in email and payment systems, topic-enforcement guardrails on customer service chatbots, and PII detection layers that redact sensitive personal data before it reaches a model or its logs.
How Do AI Guardrails Work?
A guardrail runs a classifier at one or more checkpoints in the AI pipeline, typically on the user's input and again on the model's output. The classifier outputs a confidence score between 0 and 1 for each risk category it monitors. When that score crosses a set threshold, the system takes a defined action such as blocking the content, returning a refusal message, or routing the item to a human reviewer.
Can AI Guardrails Be Bypassed?
Guardrails can be challenged through prompt injection attacks, where users craft inputs designed to confuse or override the classifier. No single classifier catches every attempt, which is why production systems layer input-side checks, output-side checks, and sometimes human review queues. Keeping training data fresh and tuning thresholds regularly reduces the window of vulnerability.
Are AI Guardrails Required by Law?
The EU AI Act, in force since 2024 with phased obligations through 2027, requires conformity assessments and human oversight for AI classification systems designated as high-risk. While guardrails help satisfy those requirements, they do not replace the documented audit trails and human review processes that regulators expect. Compliance obligations vary by jurisdiction and use case, so legal advice specific to your product is advisable.