LLM Output Safety Classification - How an LLM Output Safety Classifier Protects Users
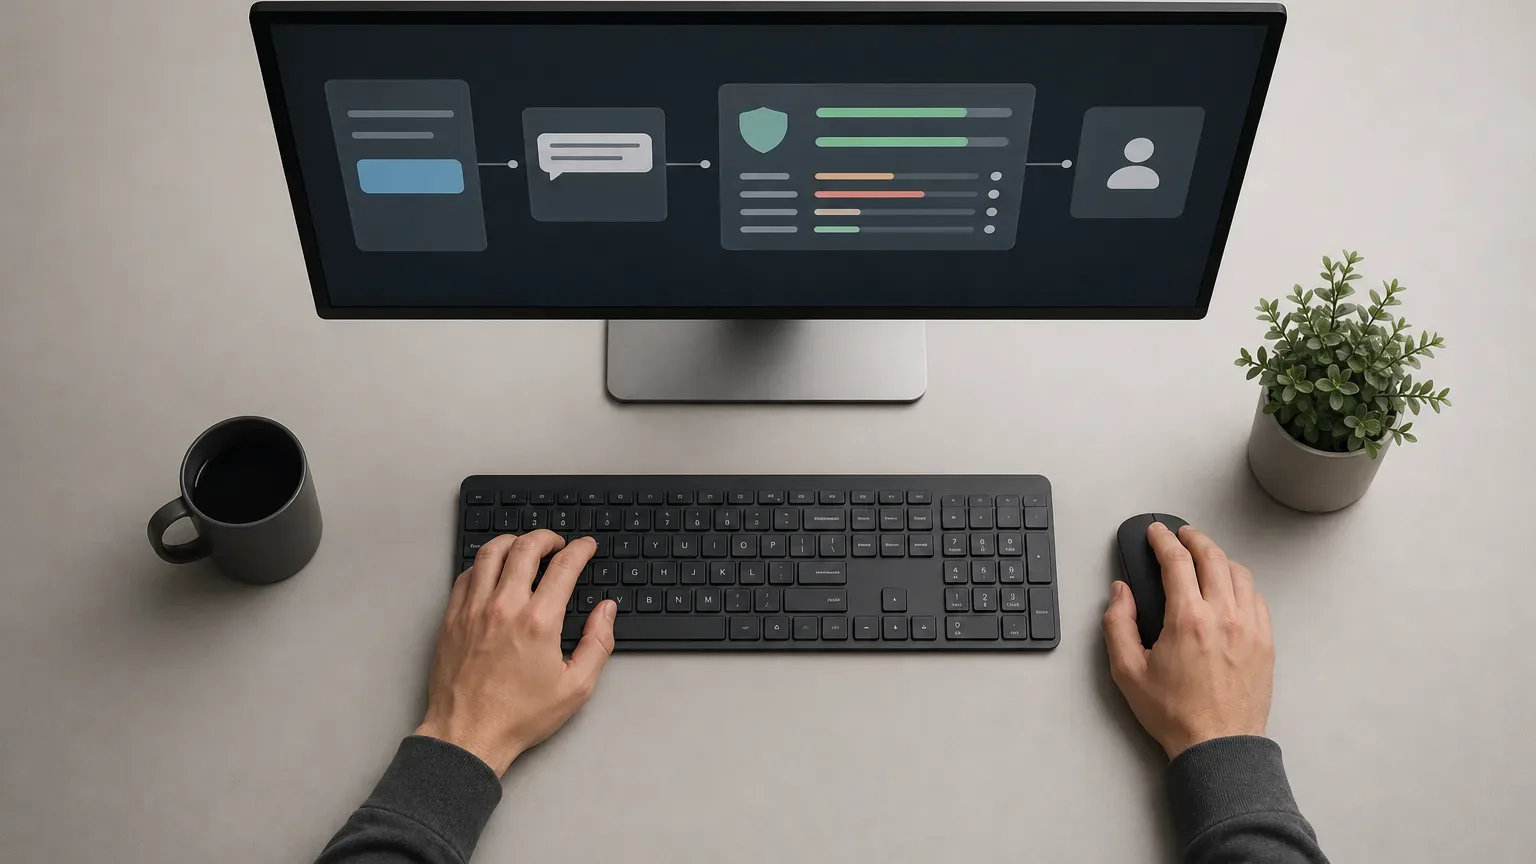
Every time a chatbot generates a response, there is a window between the model producing text and a user reading it. An LLM output safety classifier sits inside that window, reading the generated text and assigning it to one or more predefined categories, such as safe, harmful, off-topic, or policy-violating, before the response ever reaches the screen. The whole process typically completes in under 100 milliseconds for cloud-hosted classifiers, meaning users rarely notice it happening.
This layer of automated review has become a practical necessity. Large platforms process hundreds of millions of content items per day using automated classifiers before any human reviewer sees them. Catching a harmful response after the fact is far more damaging than blocking it before delivery.
What an LLM Output Safety Classifier Actually Does
The classifier reads the finished text that a language model has produced and scores it against a set of risk categories. Common categories include hate speech, instructions for violence, sexual content, personally identifiable information, and factually dangerous medical or legal advice. Each category receives a confidence score: a probability value between 0 and 1 indicating how likely the text belongs to that class.
A threshold, typically set at 0.5 by default, determines whether the classifier flags a response or passes it through. Many production systems lower or raise that threshold depending on context. A children's education platform might set a very low threshold for any adult-content category, accepting more false positives in exchange for stricter filtering.
Multi-Label vs. Multi-Class Safety Checks
Some classifiers use multi-label classification, where a single response can receive two or more labels at the same time. A reply might be flagged as both off-topic and mildly aggressive simultaneously. Others use multi-class classification, where each response receives exactly one label from a defined list. Choosing between these approaches depends on how granularly a team needs to route or escalate flagged content.
Where the Classifier Sits in a Chatbot Pipeline
Output classifiers function as a guardrail: an AI safety layer that inspects the language model's generated text to block harmful, non-compliant, or off-topic content before it reaches users. They sit downstream of the generative model but upstream of the user interface. Some systems chain multiple classifiers in sequence, running a fast binary safe/unsafe check first and then routing uncertain responses to a more detailed multi-category model.
Why Not Just Use the LLM Itself to Check Its Own Output
Dedicated classifiers are generally faster and cheaper to run at scale than prompting a large language model to evaluate its own responses. Running a lightweight classification model typically costs an order of magnitude less per inference than an equivalent LLM API call. For a service handling millions of daily interactions, that difference is significant.
There is also a reliability argument. A generative model asked to self-assess can be manipulated through clever prompt construction, a vulnerability recognized as a top security risk for LLM-powered applications by OWASP in its LLM Top 10. A separately trained classifier has no conversational state to exploit and evaluates text purely against its training distribution.
That said, classifiers lack the contextual flexibility of a large language model. A nuanced response discussing the history of a violent conflict might be flagged incorrectly by a blunt category model. Many teams combine both approaches: a fast classifier for high-volume decisions and an LLM-based review for borderline cases.
How Accurate Are Output Safety Classifiers
Modern AI classifiers commonly report 95–99% accuracy on benchmark datasets, though real-world performance depends heavily on domain, data freshness, and threshold settings. A classifier trained on social media toxicity data will not automatically transfer well to a medical chatbot context without retraining or fine-tuning.
False positives (safe responses incorrectly blocked) create friction for users. False negatives (harmful responses incorrectly passed through) create risk. Production teams targeting fraud and harm prevention typically aim for a false positive rate below 1–5%, but the right balance differs by use case. A mental health support chatbot will accept more friction to minimize any chance of harmful advice slipping through.
Training Data Requirements
Most supervised text classifiers need at least a few hundred labeled examples per category to achieve reliable performance. For a safety classifier covering ten distinct risk categories, that means collecting and labeling thousands of real or synthetic examples. Zero-shot and few-shot approaches using large language models as the backbone can operate with fewer examples, but they carry the speed and cost trade-offs described above.
Building a bespoke supervised safety classifier from scratch, covering data labeling, training, evaluation, and deployment, typically costs $5,000–$50,000 or more depending on data complexity and team location. Teams that cannot justify that investment often start with a managed API, where indicative costs run $0.50–$5.00 per 1,000 calls depending on model size and input length.
Handling PII and Sensitive Data in Outputs
AI PII classifiers can identify common personal data types, including names, email addresses, phone numbers, and national ID numbers, within a generated response. This matters because a language model trained on large corpora can sometimes reproduce fragments of training data or infer sensitive details from context. An output classifier catching PII before delivery prevents a chatbot from inadvertently leaking personal information.
Combining classifier-based PII detection with rule-based pattern matching, for example, regex patterns for credit card formats, produces more reliable coverage than either approach alone. Human audit remains necessary for high-stakes use cases; no classifier should be relied upon for 100% detection in a regulated environment.
Regulatory Pressure and Compliance
The EU AI Act, in force from 2024 with phased obligations running through 2027, designates certain AI classification systems as high-risk, requiring conformity assessments and documented human oversight. Chatbots deployed in healthcare, hiring, or financial advice contexts are likely to fall under heightened scrutiny. An auditable output safety layer, with logged confidence scores and flagged decisions, makes compliance evidence far easier to produce.
Organizations should verify their specific compliance deadlines directly with legal counsel, as the legislation's phased timelines continue to develop. The general direction is clear: automated safety classification is moving from a best practice to a documented requirement in many regulated sectors.
Tuning and Maintaining a Safety Classifier Over Time
Safety classifiers degrade without maintenance. User behavior shifts, new jargon emerges for harmful content, and adversarial users actively probe for gaps. A classifier that performs well at launch will show measurable accuracy drops within months if left static.
Production teams typically implement continuous evaluation pipelines that sample live traffic, route ambiguous cases to human reviewers, and feed confirmed labels back into periodic retraining cycles. Setting up that infrastructure early, before scale makes it expensive to retrofit, is the single most impactful operational decision a team can make when deploying an LLM output safety classifier.
Frequently Asked Questions
LLM Output Safety Evaluation
LLM output safety evaluation is the process of systematically assessing a language model's generated responses for harmful, off-policy, or non-compliant content. It typically involves an automated classifier that scores each response against risk categories such as hate speech, dangerous advice, or PII exposure, producing a confidence score between 0 and 1. Human review is layered on top for borderline or high-stakes cases.
What Is the Difference Between an Input Guardrail and an Output Safety Classifier?
An input guardrail inspects what the user sends to a chatbot, blocking prompt injection attempts or off-topic queries before the language model responds. An output safety classifier works on the other side, reading the text the model has already generated and deciding whether it is safe to deliver. Many production systems run both, catching risks at entry and again before delivery.
How Do You Set the Right Threshold for an Output Safety Classifier?
The default threshold of 0.5 means the classifier flags any response where the confidence score for a harmful category exceeds 50%. In practice, high-risk applications such as children's platforms or health services lower that threshold to catch more borderline content, accepting more false positives. Lower-risk applications may raise the threshold to reduce friction. Threshold tuning should be guided by labeled test sets and reviewed whenever user behavior or content patterns change.
Can an Output Safety Classifier Catch Hallucinations or Factually Wrong Responses?
A standard safety classifier is trained to detect harmful or policy-violating content, not factual errors. Catching hallucinations requires a separate factual consistency model or a retrieval-augmented verification step. Some teams run both layers in parallel, using a safety classifier for policy compliance and a grounding checker for factual accuracy.
How Much Data Does It Take to Train a Custom Output Safety Classifier?
Most supervised text classifiers need at least a few hundred labeled examples per risk category to reach reliable performance. A classifier covering ten categories therefore needs thousands of labeled samples in total. Teams with limited labeled data can start with a zero-shot or few-shot approach using a large language model as the backbone, though this carries higher per-inference cost and latency compared with a dedicated lightweight classifier.