Multi-Class vs. Multi-Label Classification Explained
Two Different Problems That Look Similar
Both multi-class and multi-label classification are ways of sorting data into categories, but they answer fundamentally different questions. Understanding which type fits your problem is the first practical step before choosing a model, gathering training data, or evaluating results. Getting this wrong leads to architectures that are harder to fix later.
The clearest way to frame the difference: multi-class classification gives every input exactly one label, while multi-label classification lets a single input carry several labels at once.
What Is Multi-Class Classification?
Multi-class classification is a task where each input is assigned exactly one label from three or more possible classes. A model trained this way treats every category as mutually exclusive: if a news article is classified as "Sports," it cannot also be "Finance" or "Politics" at the same time.
This makes the output straightforward to interpret. Each prediction is a single choice. The confidence scores for all candidate classes in a multi-class setup sum to 1.0, so a model expressing high confidence in one class is automatically expressing lower confidence in the others.
A common real-world example is handwritten digit recognition. Each image shows exactly one digit from 0 to 9, and the model picks the most likely one. Medical imaging that diagnoses a chest X-ray as one of several defined disease states works the same way.
When Multi-Class Is the Right Choice
Choose multi-class when your categories are genuinely exclusive and exhaustive. A support ticket routing system that sends each request to exactly one department is a natural fit. So is a food classification app that labels a photo as one dish from a defined menu.
The simpler output also makes evaluation easier. Accuracy, precision, recall, and F1 scores can all be applied straightforwardly per class or averaged across them.
Multi-Label Classification Explained
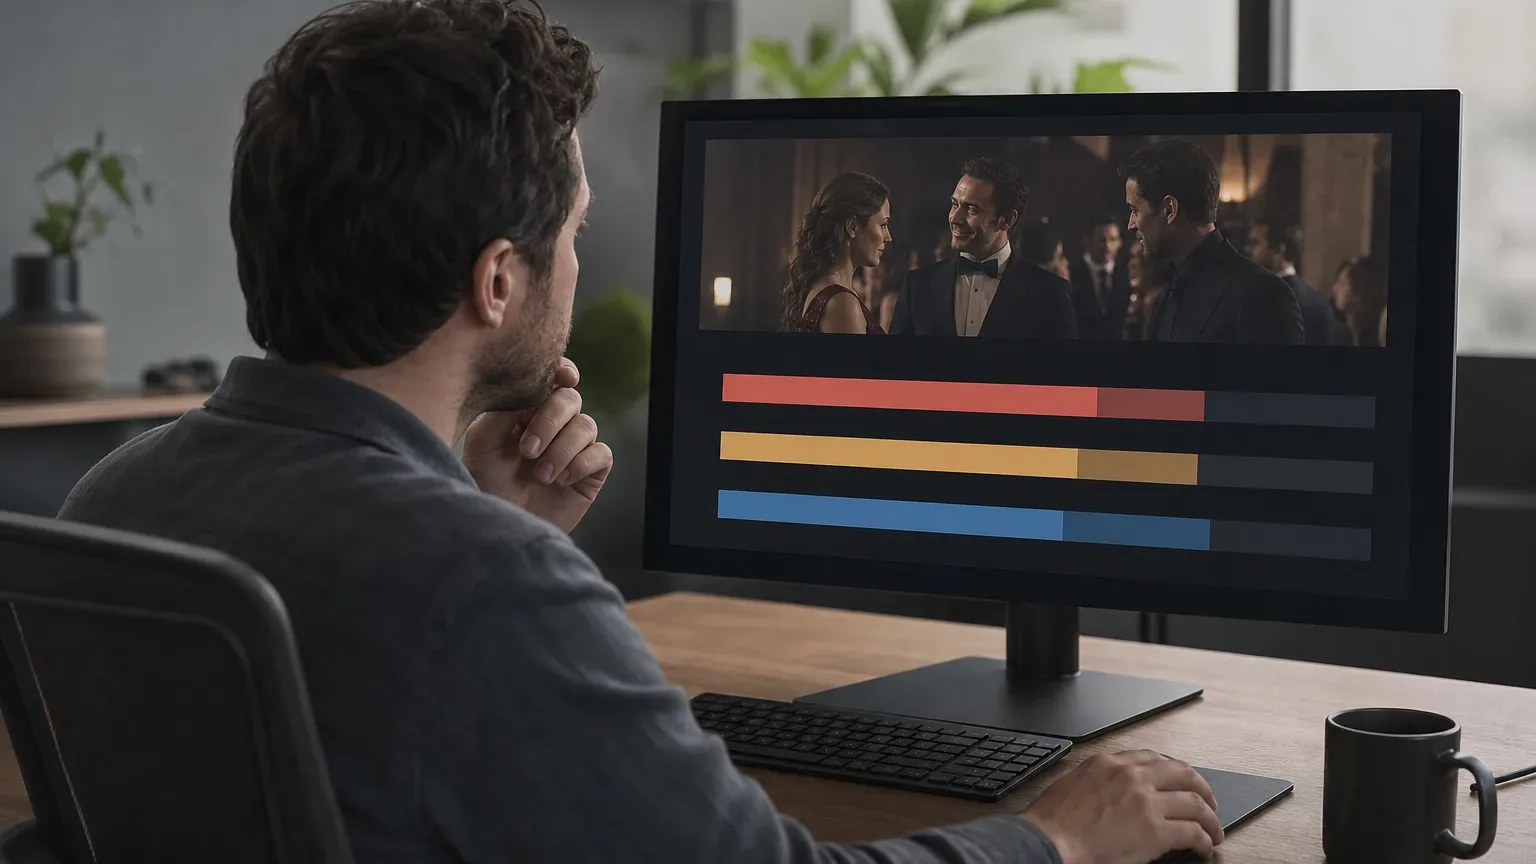
Multi-label classification is a task where a single input can be assigned two or more labels simultaneously. Each label is scored independently, meaning a piece of content can belong to several categories at once without any mutual exclusion.
This structure matches many real-world situations more accurately than forcing a single-category choice. A movie is simultaneously an "Action," "Comedy," and "Romance" film. A patient report might flag both "elevated blood pressure" and "abnormal glucose." In multi-label setups, each label gets its own confidence score between 0 and 1, and those scores do not sum to 1.0 the way they do in multi-class systems.
Because the labels are independent, a document could score above the threshold on three labels or just one, depending on what the content contains. The threshold, commonly 0.5 by default, is applied separately to each label rather than selecting the single highest scorer.
Training Data Needs
Most supervised text classifiers require at least a few hundred labeled examples per class to achieve reliable performance. In multi-label setups, that requirement applies to each label, and some label combinations may appear rarely in the training set. Sparse combinations push teams toward zero-shot or few-shot models that can generalize from fewer examples, though those approaches trade precision for flexibility.
Multi-Class vs. Multi-Label - the Core Differences
The table below captures the structural distinctions at a glance.
| Factor | Multi-Class | Multi-Label |
|---|---|---|
| Labels per input | Exactly one | One or more |
| Classes mutually exclusive | Yes | No |
| Confidence scores | Sum to 1.0 across classes | Independent per label |
| Threshold logic | Pick highest-scoring class | Apply threshold to each label separately |
| Evaluation metric | Accuracy, macro/micro F1 | Hamming loss, subset accuracy, per-label F1 |
Choosing the wrong framing creates real problems. Training a multi-class model on data that naturally has overlapping categories forces artificial choices that introduce noise. Conversely, applying a multi-label approach to a genuinely exclusive problem can complicate deployment and inflate the number of model outputs without benefit.
Examples of Multi-Label Classification in Practice
Content tagging is the most visible use case. A blog post about a remote work productivity tool might receive the tags "Technology," "Business," and "Lifestyle" simultaneously. A streaming platform assigns genre tags such as "Thriller," "Based on True Events," and "International" to a single film.
E-commerce search relies on multi-label classification to associate products with multiple relevant attribute categories. A pair of running shoes might be labeled "Men's," "Trail," "Waterproof," and "Sale" at the same time so it surfaces under any of those filters.
Email processing systems often use multi-label logic as well. A message can be both "Urgent" and "Requires Approval" and "Finance-Related" without any conflict. Forcing those tags into a mutually exclusive system would cause some relevant signals to be discarded.
In healthcare NLP, clinical notes frequently contain references to multiple active conditions, medications, or procedure codes. Multi-label classifiers extract all relevant codes at once rather than selecting one. These systems sit within a broader AI safety context: the EU AI Act, in force from 2024 with phased obligations running through 2027, designates certain AI classification systems used in healthcare as high-risk, requiring conformity assessments and human oversight.
How Confidence Scores Work Differently in Each Type
A confidence score is a probability value between 0 and 1 output by a classifier indicating how likely the input belongs to a given class. In multi-class systems, those scores are linked: raising confidence in one class lowers it in others because the outputs are normalized to sum to 1.0.
In multi-label systems, each label has its own independent confidence score between 0 and 1. A document can carry a score close to 1 on one label and a score close to 1 on a second label simultaneously. A threshold is applied separately to each, so the number of labels attached to an input varies based on what the model detects in the content.
Practitioners calibrating a multi-label system often adjust thresholds per label based on the cost of false positives versus false negatives for that specific category. A content moderation label for severe policy violations might use a lower threshold so fewer harmful items slip through. A recommendation tag with low stakes might use a higher threshold to keep results precise.
Picking the Right Architecture for Your Use Case
The decision comes down to one question: can one input legitimately belong to more than one category at the same time? If the answer is yes in any realistic scenario, multi-label is the right choice.
Dedicated classifiers of either type are generally faster and cheaper to run at scale than prompting a large language model for the same decision. A lightweight classification model typically costs an order of magnitude less per inference than an equivalent LLM API call. For high-volume pipelines processing millions of items, that difference is significant.
Broadly available managed classifier APIs cost roughly $0.50–$5.00 per 1,000 calls depending on model size, provider, and input length. For organizations with sufficient labeled data and specific accuracy requirements, a custom supervised project runs approximately $5,000–$50,000 or more, covering data labeling, training, evaluation, and deployment. Most cloud-hosted text classifiers return results in under 100 milliseconds at standard input lengths, making either architecture viable for real-time applications.
Frequently Asked Questions
What Is Multi-class Classification?
Multi-class classification is a task where each input is assigned exactly one label from three or more possible categories. The classes are mutually exclusive, so a model can only pick one label per input. Common examples include digit recognition, disease diagnosis from imaging, and support ticket routing.
How Does Multi-label Classification Work?
Multi-label classification lets a single input receive two or more labels at the same time. Each label is scored independently with a confidence value between 0 and 1, and a threshold is applied separately to each label to decide whether it is assigned. A news article could be tagged as both 'Technology' and 'Business' without conflict.
What Is the Main Difference Between Multi-class and Multi-label Classification?
The core difference is exclusivity. In multi-class classification, each input gets exactly one label and the confidence scores across all classes sum to 1.0. In multi-label classification, an input can carry several labels simultaneously, and each label's confidence score is independent of the others. Choosing the wrong type for your data leads to avoidable errors in training and evaluation.
What Are Some Real Examples of Multi-label Classification?
Common examples include blog post tagging where a single article receives multiple topic tags, e-commerce product categorization where one item is labeled under several attributes at once, email classification that flags a message as both 'Urgent' and 'Finance-Related,' and clinical NLP systems that extract multiple diagnosis codes from a single patient note.
How Do Confidence Scores Differ Between Multi-class and Multi-label Classifiers?
In multi-class systems, confidence scores across all candidate classes are normalized so they sum to 1.0, meaning higher confidence in one class automatically reduces confidence in the others. In multi-label systems, each label has its own independent confidence score between 0 and 1, and scores do not sum to any fixed total. Thresholds are applied per label rather than selecting the single highest-scoring class.